The legacy pipeline
Over the past 20 years, the graphics pipeline has evolved to reach its now familiar state. As independent hardware vendors (IHVs) focus on an ever-widening battle of core count, memory capacity, and bandwidth, certain fixed-function bottlenecks have become apparent in the geometric processing model. Figure 1. The legacy graphics pipeline. Blue-tinted stages are fixed-function. Green-tinted stages are programmable shaders.
The Mesh Shader pipeline
The Mesh Shader pipeline targets these legacy graphics pipeline limitations. First of all, it removes the IA and tessellator from the pipeline. This is intended to maximize the shader wave launch rate and shift IA to shader code that can scale with GPUs. This can help saturate GPU cores and keep pressure on the PA. This pipeline also provides the ability to cull workloads at various points in the pipeline. Amplification shaders may be used to do low-granularity culling, such as against grouped objects, instances, or meshlets. Mesh Shaders can do culling at a per-primitive granularity. This provides a path for discarding trivially cullable primitives early and often - saving precious computation, memory bandwidth, and PA throughput. Figure 2. The stages of the Mesh Shader pipeline. Green-tinted stages are programmable. Blue-tinted stages are fixed-function.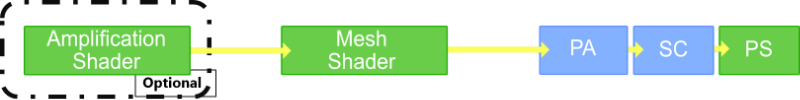
Mesh Shaders
Mesh Shaders were designed to provide a level of generality to the geometry pipeline only found in compute shaders. This gives the developer full control over each thread’s workload. Moving index and vertex attribute fetches to shader code removes the dependency on fixed-function hardware, maximizing wave launch rates and allowing IA to scale with the rest of the GPU. Their ability to dynamically specify vertex and primitive export counts opens the gate for efficient, onchip support for primitive culling. This can be done per-meshlet or per-primitive against any arbitrary culling criteria inside the Mesh Shader. This allows shaders to defer vertex attribute fetches and shading until the end of the pipeline, after several layers of culling have already been performed.Amplification Shaders
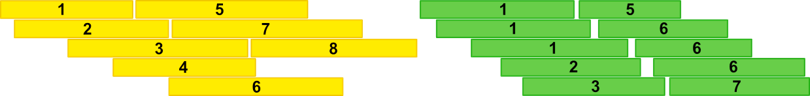
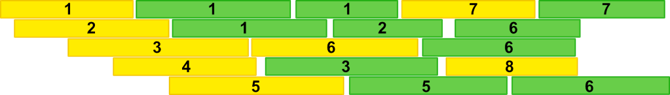
Compute shaders are regularly used to preprocess resources, followed up with draw calls that consume their results by using ExecuteIndirect. This is a common technique for many forms of per-view culling. This has a couple of subtle drawbacks that could be optimized with proper hardware support. For one, the compute shader instances must write their data to global memory. This incurs fetch latency and makes it subject to GPU-wide memory bandwidth contention. Secondly, if the compute producer and graphics consumer are consecutive operations, the GPU must wait for all compute shader instances to retire before launching the consuming draw calls. This is caused by an unordered access view (UAV) resource barrier that must enforce all compute shader writes to the final UAV are completed before any shader can consume it. Figure 3. Simplified wave scheduling visualization of a compute shader with immediately subsequent ExecuteIndirect “DispatchMesh” draw. Compute shader waves (yellow) are separated from Mesh Shader wave (green) execution by a pipeline stall because of a UAV barrier. The numbered IDs relate the invoking computer shader threadgroup to its cluster of Mesh Shader children.